An Open-World Benchmark for Long-Horizon Stability of Interactive World Models
An Open-World Benchmark for Long-Horizon Stability of Interactive World Models
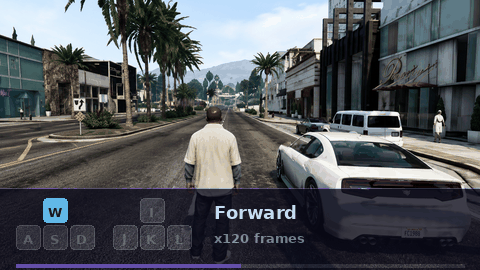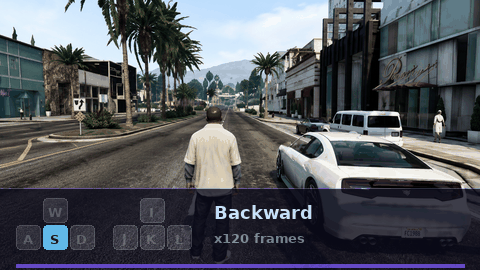
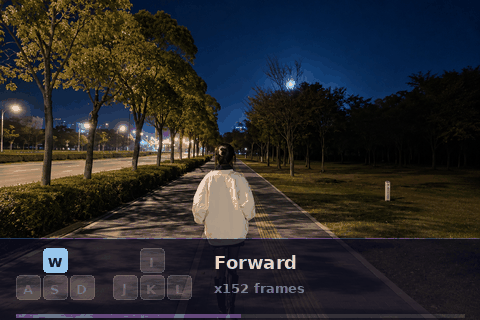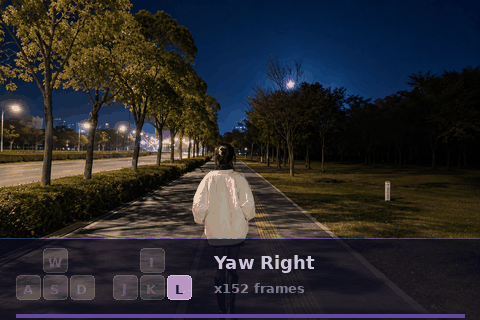
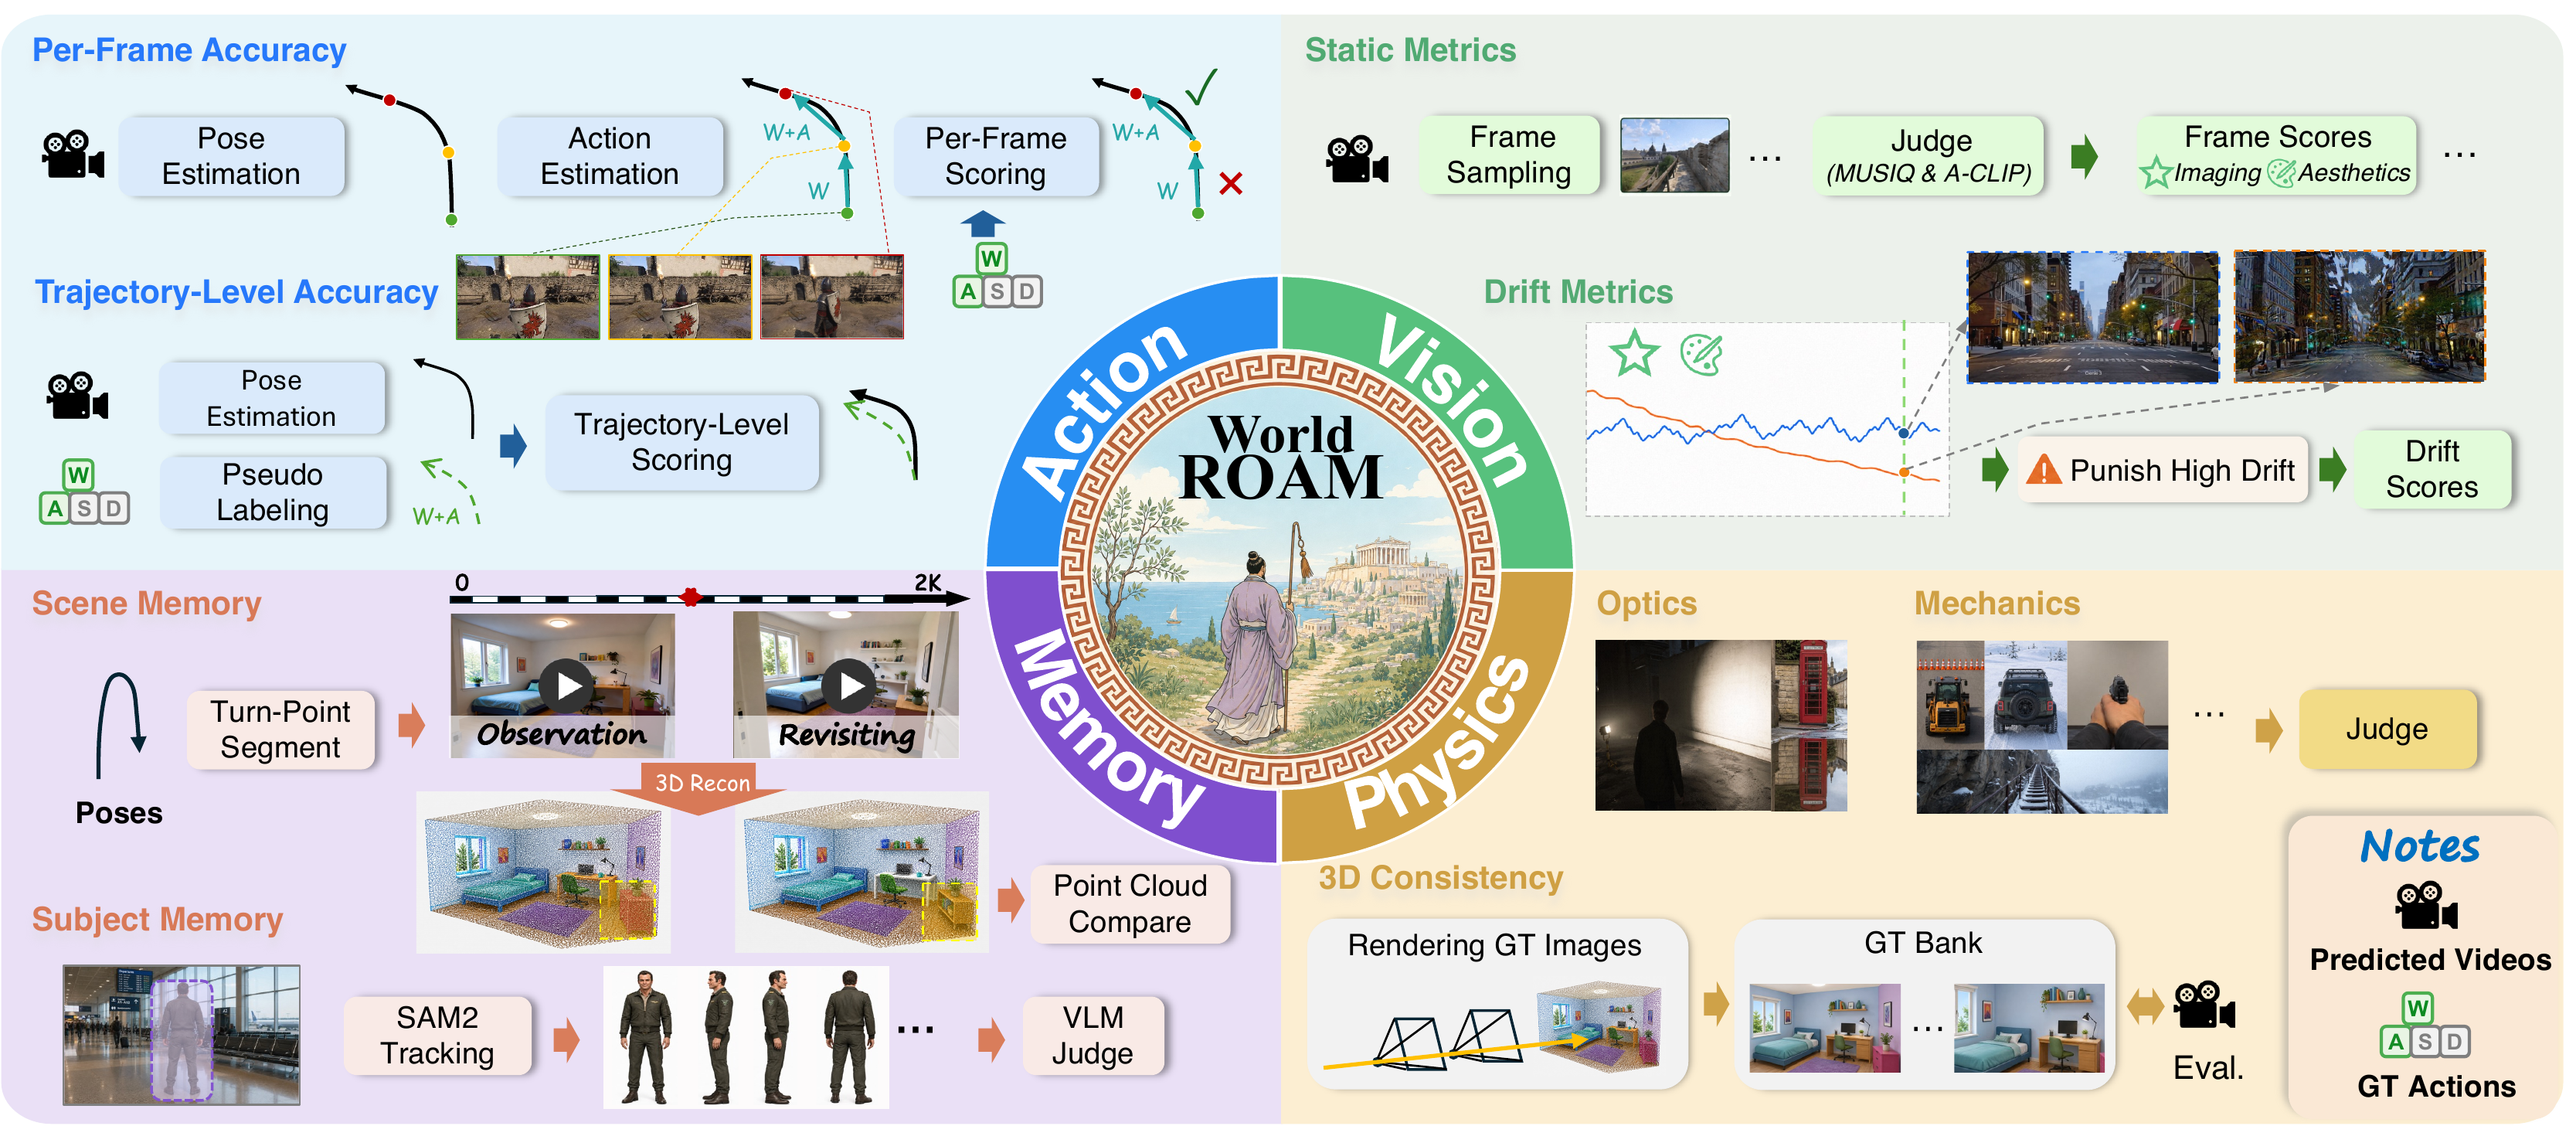
A comprehensive benchmark for evaluating interactive world models which bridging four critical gaps: keystroke-level action accuracy, visual drift, interaction physics, and trajectory-aware memory assessment.
Frame-level action evaluation bypasses the cross-model semantic scale disparity inherent in trajectory evaluation and reveals per-step fidelity failures hidden by overall path alignment.
Per-frame aesthetic and imaging quality scores assess generation fidelity. Temporal drift metrics quantify progressive degradation invisible to single-frame or video-average measures.
Covers mechanics—collision, clipping, deformation, gravity—optics—reflection and shadow—and 3D consistency across generated frames, gated by validity check.
3D point-cloud reconstruction decouples memory from action-following drift, separately measuring retention and anti-hallucination—far more faithful than frame-pair comparison.
WorldRoam-Bench is the first benchmark to provide per-frame action metric, visual drift, interaction physics, and trajectory-aware scene/subject memory for interactive world models.
| Benchmark | Eval. Metrics | Eval. Models | Eval. Persp. | Categories | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Action Eval. Granularity |
Discrete-action Accuracy |
Visual Drift |
Interaction Physics |
Revisit Memory |
Traj.-Aware Memory |
Time Scale/Video |
Open- Source |
Closed- Source |
First- Person |
Third- Person |
Game World |
Real World |
|
| WildWorld | Segment | ✕ | ✕ | ✕ | ✕ | ✕ | ~5–10s | 5 | 0 | ✔ | ✕ | ✔ | ✕ |
| iWorld-Bench | Trajectory | ✕ | ✕ | ✕ | ✔ | ✕ | ~5–10s | 10+ | 0 | ✔ | ✕ | ✔ | ✔ |
| WorldOlympiad | Multi-chunk | ✕ | ✕ | ✔ | ✕ | ✕ | ~10s | 8 | 0 | ✔ | ✕ | ✔ | ✔ |
| MIND | Trajectory | ✕ | ✕ | ✕ | ✔ | ✕ | ~5–10s | 2 | 0 | ✔ | ✔ | ✔ | ✕ |
| WBench | Multi-turn | ✕ | ✕ | ✔ | ✔ | ✕ | ~5–10s | 10+ | 2 | ✔ | ✕ | ✔ | ✔ |
| WorldMark | Frame/segment | ✕ | ✕ | ✕ | ✔ | ✔ | 20/40/60s | 10 | 0 | ✔ | ✔ | ✕ | ✔ |
| WorldRoam-Bench (Ours) | Traj. + per-frame | ✔ | ✔ | ✔ | ✔ | ✔ | 10–60s | 10 | 2 | ✔ | ✔ | ✔ | ✔ |
Four-layer evaluation pipeline: test suite with diverse scenes → model inference → four evaluation modules (Action, Vision, Physics, Memory) → unified leaderboard with per-dimension rankings.
1000+ test cases spanning 1st-person and 3rd-person perspectives across Indoor, Nature, and Urban scenes, covering Memory, Action Following, Visual Quality, and Interaction Physics evaluations.
We evaluate 10+ interactive world models spanning both open-source and closed-source models. Is your model missing from the list? Submit it to the leaderboard and see how it stacks up!
Comprehensive evaluation of 10+ interactive world models across action following, visual quality, interaction physics, and memory consistency.
| # | Model | Total ↑ | Action Following | Visual Quality | Interaction Physics | Memory | ||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Score ↑ | Act Acc ↑ | Part Acc ↑ | TrajScore ↑ | nATEt ↓ | nATEr ↓ | Score ↑ | Aesth ↑ | DriftA ↓ | Imaging ↑ | DriftI ↓ | Score ↑ | Mech ↑ | Optics ↑ | 3D Con ↑ | Score ↑ | Ret ↑ | Anti-Halluc ↑ | |||
| 🥇 |
Genie 3
Closed-Source
|
70.32 | 76.31 | 62.04 | 78.06 | 88.83 | 11.48 | 10.85 | 66.21 | 53.41 | 17.22 | 54.53 | 25.87 | 66.67 | 61.50 | 60.60 | 77.90 | 72.09 | 73.93 | 77.44 |
| 🥈 |
Lyra 2.0
Open-Source
|
69.61 | 90.82 | 90.85 | 93.82 | 87.78 | 9.61 | 14.83 | 69.61 | 59.62 | 22.63 | 60.82 | 19.36 | 51.52 | 4.80 | 69.10 | 80.65 | 66.49 | 62.25 | 79.45 |
| 🥉 |
Happy Oyster
Closed-Source
|
68.53 | 88.22 | 85.90 | 89.96 | 88.80 | 11.02 | 11.37 | 66.49 | 55.93 | 19.15 | 49.04 | 19.87 | 61.40 | 45.50 | 67.50 | 71.21 | 58.00 | 55.11 | 71.29 |
| 4 |
HY-World 1.5
Open-Source
|
63.97 | 87.38 | 83.21 | 88.49 | 90.44 | 8.63 | 10.49 | 66.06 | 58.22 | 27.06 | 55.11 | 22.04 | 40.43 | 0.00 | 48.80 | 72.50 | 62.02 | 59.34 | 71.26 |
| 5 |
LingBot-World 2.0
Open-Source
|
63.90 | 90.74 | 88.95 | 96.30 | 86.98 | 6.85 | 19.18 | 68.55 | 59.93 | 24.89 | 61.57 | 22.43 | 43.52 | 3.80 | 56.60 | 70.17 | 52.80 | 53.12 | 60.01 |
| 6 |
Matrix-Game 3.0
Open-Source
|
60.34 | 91.34 | 88.77 | 94.45 | 90.79 | 9.24 | 9.17 | 68.70 | 56.50 | 26.25 | 64.77 | 20.24 | 25.56 | 0.00 | 17.20 | 59.49 | 55.76 | 59.24 | 59.78 |
| 7 |
SANA-WM-AR
Open-Source
|
59.37 | 75.73 | 71.56 | 76.66 | 78.96 | 23.23 | 18.86 | 74.40 | 60.08 | 18.36 | 69.08 | 13.20 | 22.88 | 6.40 | 41.20 | 21.05 | 64.48 | 62.79 | 77.44 |
| 8 |
LingBot-World
Open-Source
|
58.77 | 90.78 | 91.17 | 94.38 | 86.80 | 9.92 | 16.47 | 69.28 | 60.81 | 21.20 | 59.96 | 22.47 | 31.08 | 3.80 | 51.20 | 38.25 | 43.93 | 38.77 | 62.16 |
| 9 |
SANA-WM
Open-Source
|
54.61 | 70.42 | 61.91 | 69.77 | 79.59 | 22.60 | 18.22 | 71.42 | 57.17 | 21.83 | 67.80 | 17.48 | 17.38 | 3.20 | 44.70 | 4.23 | 59.23 | 60.09 | 72.51 |
| 10 |
Matrix-Game 2.0
Open-Source
|
51.92 | 89.67 | 88.11 | 92.79 | 88.10 | 11.57 | 12.23 | 60.83 | 53.69 | 32.43 | 48.52 | 26.46 | 12.21 | 0.00 | 9.70 | 26.92 | 44.96 | 45.29 | 54.66 |
| 11 |
Yume 1.5
Open-Source
|
47.06 | 71.77 | 58.45 | 76.41 | 80.45 | 18.91 | 20.18 | 69.07 | 57.97 | 23.91 | 64.64 | 22.42 | 14.33 | 7.40 | 10.30 | 25.30 | 33.05 | 30.67 | 48.72 |
| 12 |
minWM
Open-Source
|
41.88 | 60.79 | 46.15 | 53.18 | 83.04 | 13.63 | 20.28 | 58.21 | 48.93 | 43.50 | 51.59 | 24.20 | 7.12 | 0.00 | 4.40 | 16.97 | 41.41 | 41.55 | 59.34 |
Until 2026.08.20
15 metrics across 4 dimensions. All scores normalized to [0, 100].
Side-by-side comparisons of model outputs across evaluation dimensions. Each pair contrasts a high-scoring result with a low-scoring one on the same scene.